01 · Problem
The good roles disappear within hours.
Job boards return hundreds of postings, most of them wrong: senior roles, clearance jobs, no sponsorship. Checking by hand doesn't scale, and every application still needs its own résumé.
It started in March 2026 as a scraper for my own job search and grew into a résumé compiler. I open-sourced it in June: a Python scraper, an Express server, and a Node sidecar that runs Gemma locally and compiles LaTeX.
The good roles disappear within hours.
Job boards return hundreds of postings, most of them wrong: senior roles, clearance jobs, no sponsorship. Checking by hand doesn't scale, and every application still needs its own résumé.
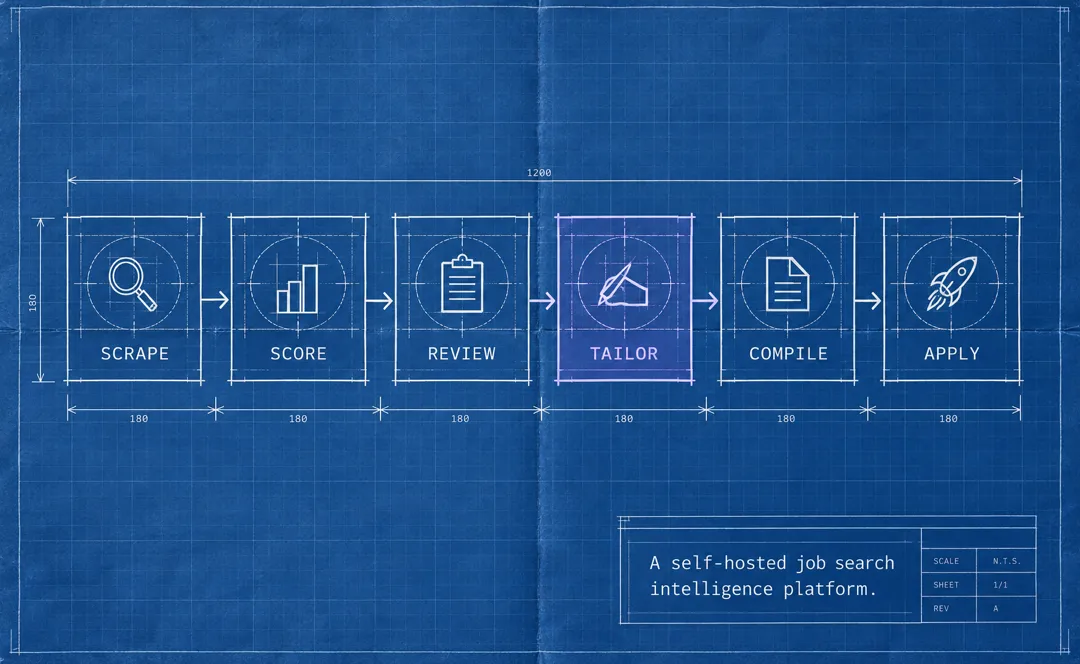
Scrape, score, tailor, compile.
Every hour a scraper pulls LinkedIn, Greenhouse and Lever postings and scores each 0–10 on keywords, location, recency and source. For jobs I pick, a local model chooses my strongest real bullets for a one-page PDF.
The hosted UI reaches your backend by URL and API key: the UI lives on Atriveo's servers, your postings and résumés stay on yours.
A 12B model will fill every field you give it. Mine kept writing until it cut off its own JSON.
Under a JSON schema, Gemma padded keyword lists and rewrote every bullet until the output was truncated. Every list is now capped in both the prompt and the schema, and each Ollama call retries with a larger token budget only when it needs one.