01 · Problem
A course project isn't a platform.
The original pipeline could stream and index events, but nothing secured a route, discovered a service, or rate-limited a client — what a real system in front of insurers actually needs.
It began in 2024 as a Kafka streaming exercise: a service literally called twitter-to-kafka-service. In 2026 I rebuilt the top of the stack around insurance policies and claims, adding service discovery, a JWT-secured gateway, and Prometheus and Grafana.
A course project isn't a platform.
The original pipeline could stream and index events, but nothing secured a route, discovered a service, or rate-limited a client — what a real system in front of insurers actually needs.
Keep the pipeline, build the platform around it.
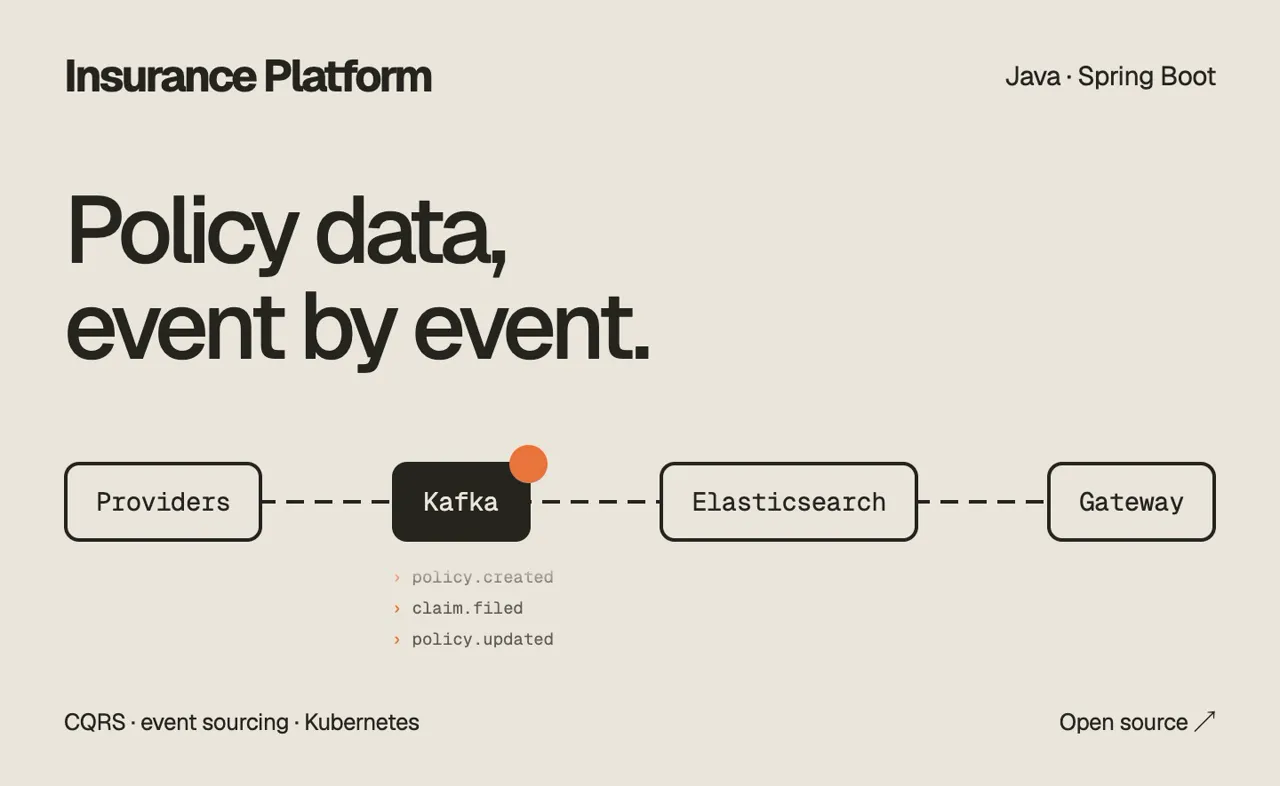
Ingestion, streaming and indexing stayed as they were. Eureka now gives services a registry instead of hard-coded URLs, a gateway checks a JWT and rate-limits each route through Redis, and Prometheus, Grafana and ELK watch all of it.
Writes go to Kafka and reads come from Elasticsearch, so the query side never blocks on the write side, or on the insurer feed behind it.
Every service still says “twitter.” The events are insurance policies now; the class names never caught up.
The write path began as a Kafka course project on tweet streams: the ingestion service is still called twitter-to-kafka-service, and its schema still has a userId field. When I rebuilt the top of the stack in 2026 (Eureka, JWT, Redis limits, Prometheus, Grafana) I left that name alone on purpose.